> ## Documentation Index
> Fetch the complete documentation index at: https://docs.openlayer.com/llms.txt
> Use this file to discover all available pages before exploring further.
# Track usage
> See what each key, user, and group is consuming and what it costs
Usage and cost show what your traffic is actually consuming. It's the reporting side of
[usage limits](/gateway/budgets-and-limits): limits set the cap, usage shows where you stand against it.
## Where to see it
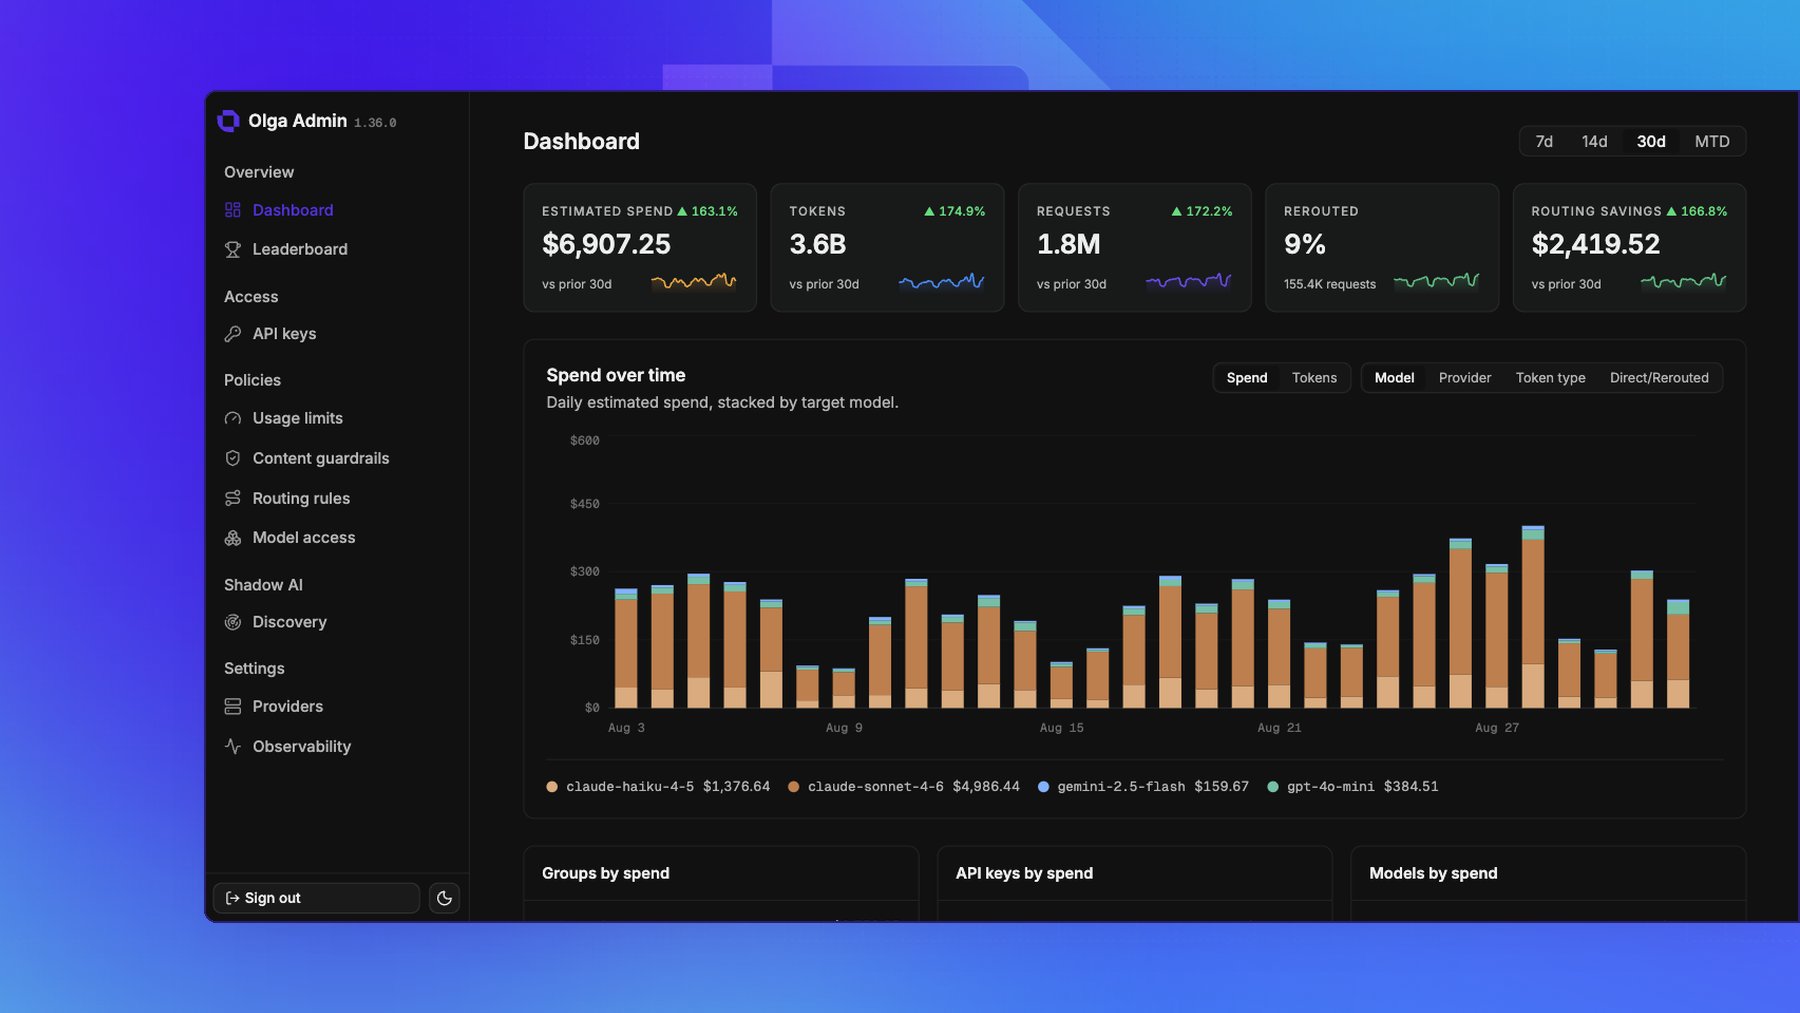
* The **Dashboard** shows the whole deployment: estimated spend, tokens, requests, how much traffic
was rerouted and what that saved, spend over time, and the top groups, keys, and models by spend.
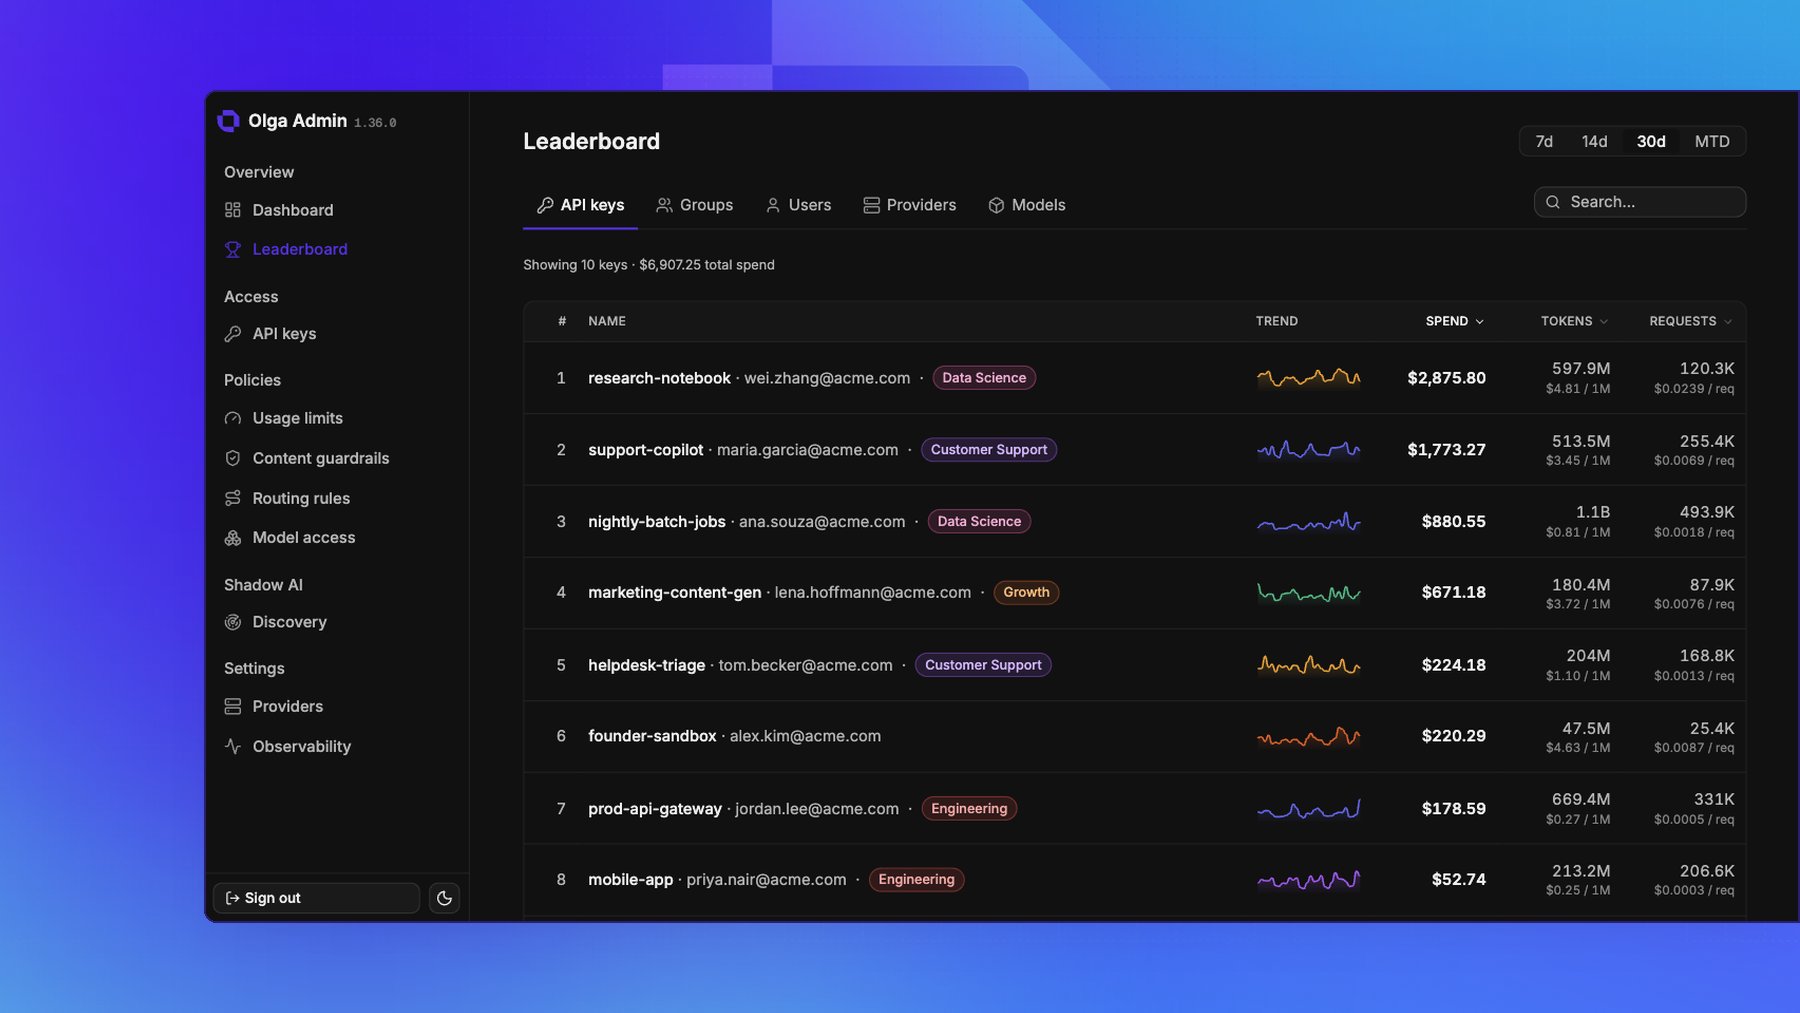
* The **Leaderboard** ranks spend, with a tab for **API keys**, **Groups**, **Users**, **Providers**,
and **Models**, so you can see where cost is coming from without opening keys one at a time.
* The **Usage limits** page shows each limit's current usage against its amount for the active window.
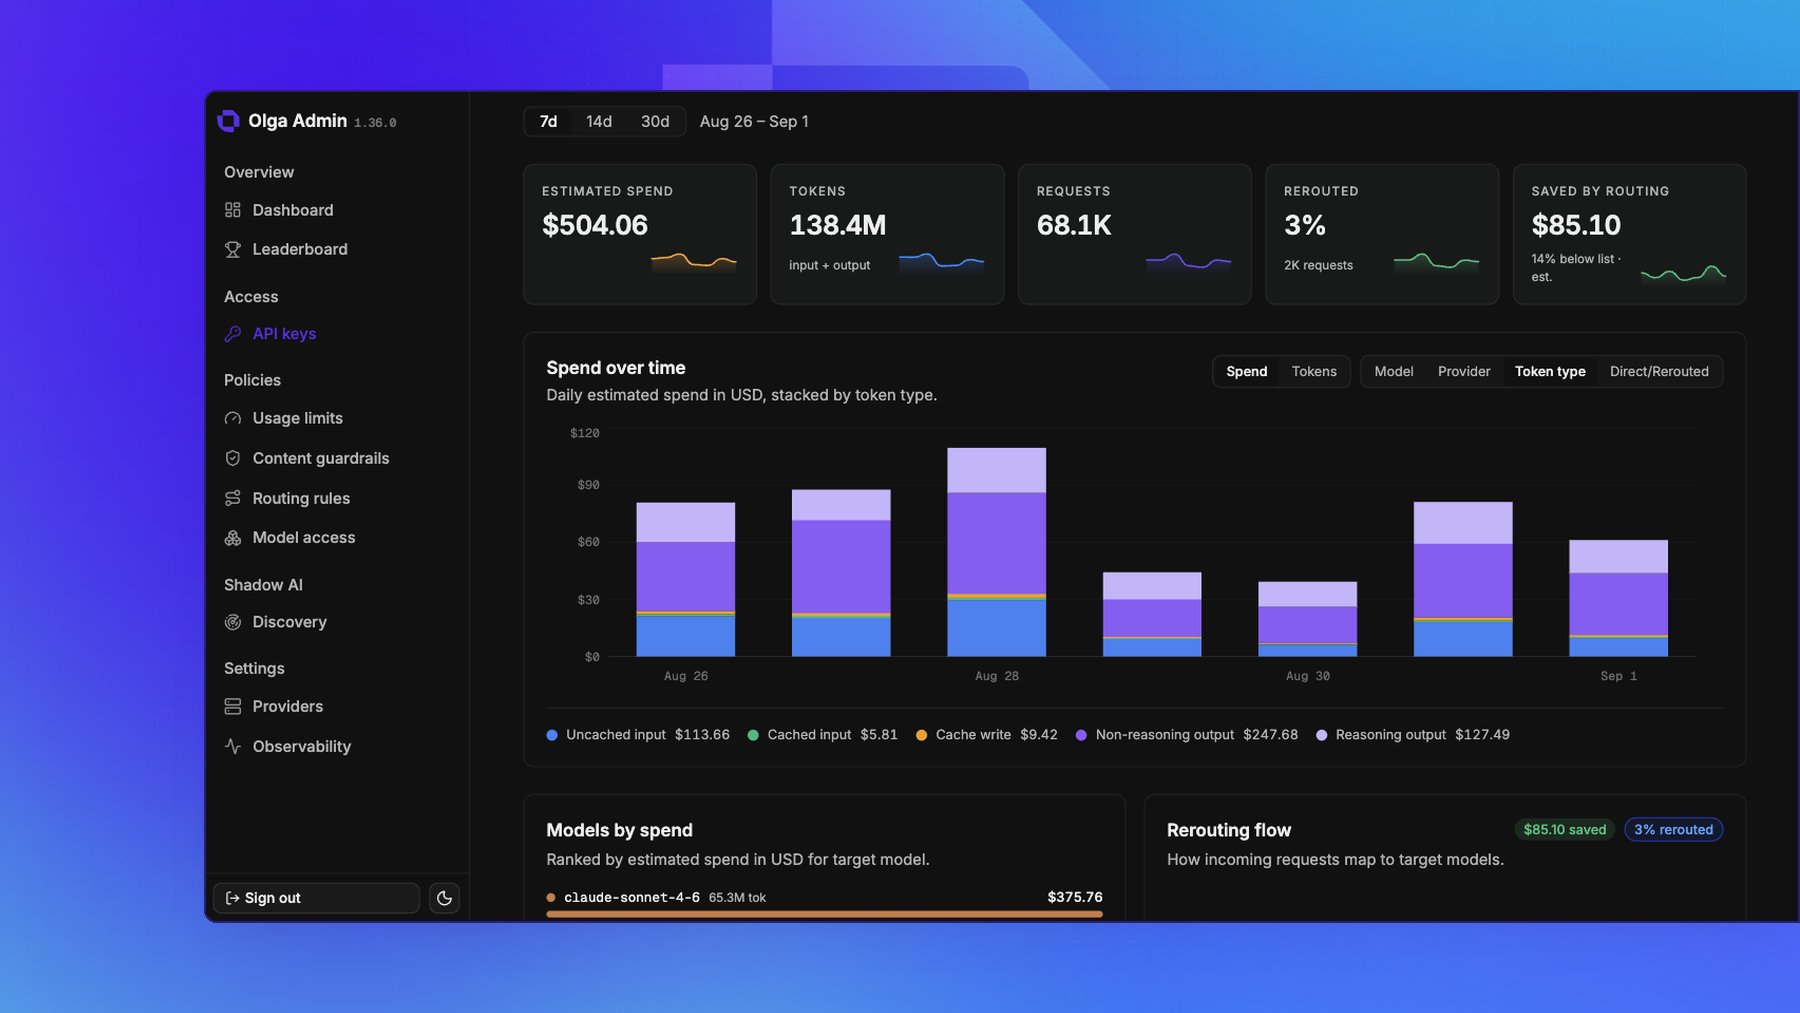
* A **key's detail** page shows requests, tokens, and estimated cost over time, broken down by model,
provider, or token type.
 ## What's tracked
For every key, the gateway records each day (UTC):
* **Requests**: how many calls the key made.
* **Tokens**, split into the five types that price differently:
* **Uncached input** and **Cached input**, the prompt tokens at standard and cache-read rates.
* **Cache write**, the input tokens charged for populating the provider's cache.
* **Non-reasoning output** and **Reasoning output**, so you can see how much of a bill is a
reasoning model thinking.
* **Estimated cost**: in USD, and split across those five token types.
* **Routing**: which incoming model and provider the caller asked for, and which target model and
provider served it.
Usage can be sliced by day, by key, or by model. On the spend chart, switch between **Spend** and
**Tokens**, and break either down by **Model**, **Provider**, **Token type**, or
**Direct/Rerouted**.
## Rerouting savings
When a [routing rule](/gateway/route-requests) sends a request to a different model than the caller
asked for, the gateway prices the same tokens twice: once at the model that actually served the
request, and once at the model the caller named. The difference is the saving from that reroute,
reported as **Saved by routing** alongside **Rerouted**, the share of requests a rule redirected.
A key's detail page also breaks this out as a rerouting flow, showing which requested model ended up
on which serving model.
A reroute onto a more expensive model shows as a negative saving, which is the signal that a rule is
costing you money rather than saving it.
## How cost is estimated
The gateway multiplies token counts by its cached per-model pricing, using the provider's separate
rates for cached input where they apply. Treat it as a close estimate for tracking and budgeting, not
as a replacement for your provider's invoice.
## Go deeper
Usage answers "how much." For request-level detail, including inputs and outputs, latency, and the
trace of each call, see [Observability](/gateway/observability).