- If you are building an AI system with OpenAI LLMs and want to evaluate it, you can use the SDKs to make Openlayer part of your workflow.
- Some tests on Openlayer are based on a score produced by an LLM judge. You can set any of OpenAI’s LLMs as the LLM judge for these tests.
Using OpenAI Agents SDK? Check out the OpenAI Agents SDK
integration page.
Evaluating OpenAI LLMs
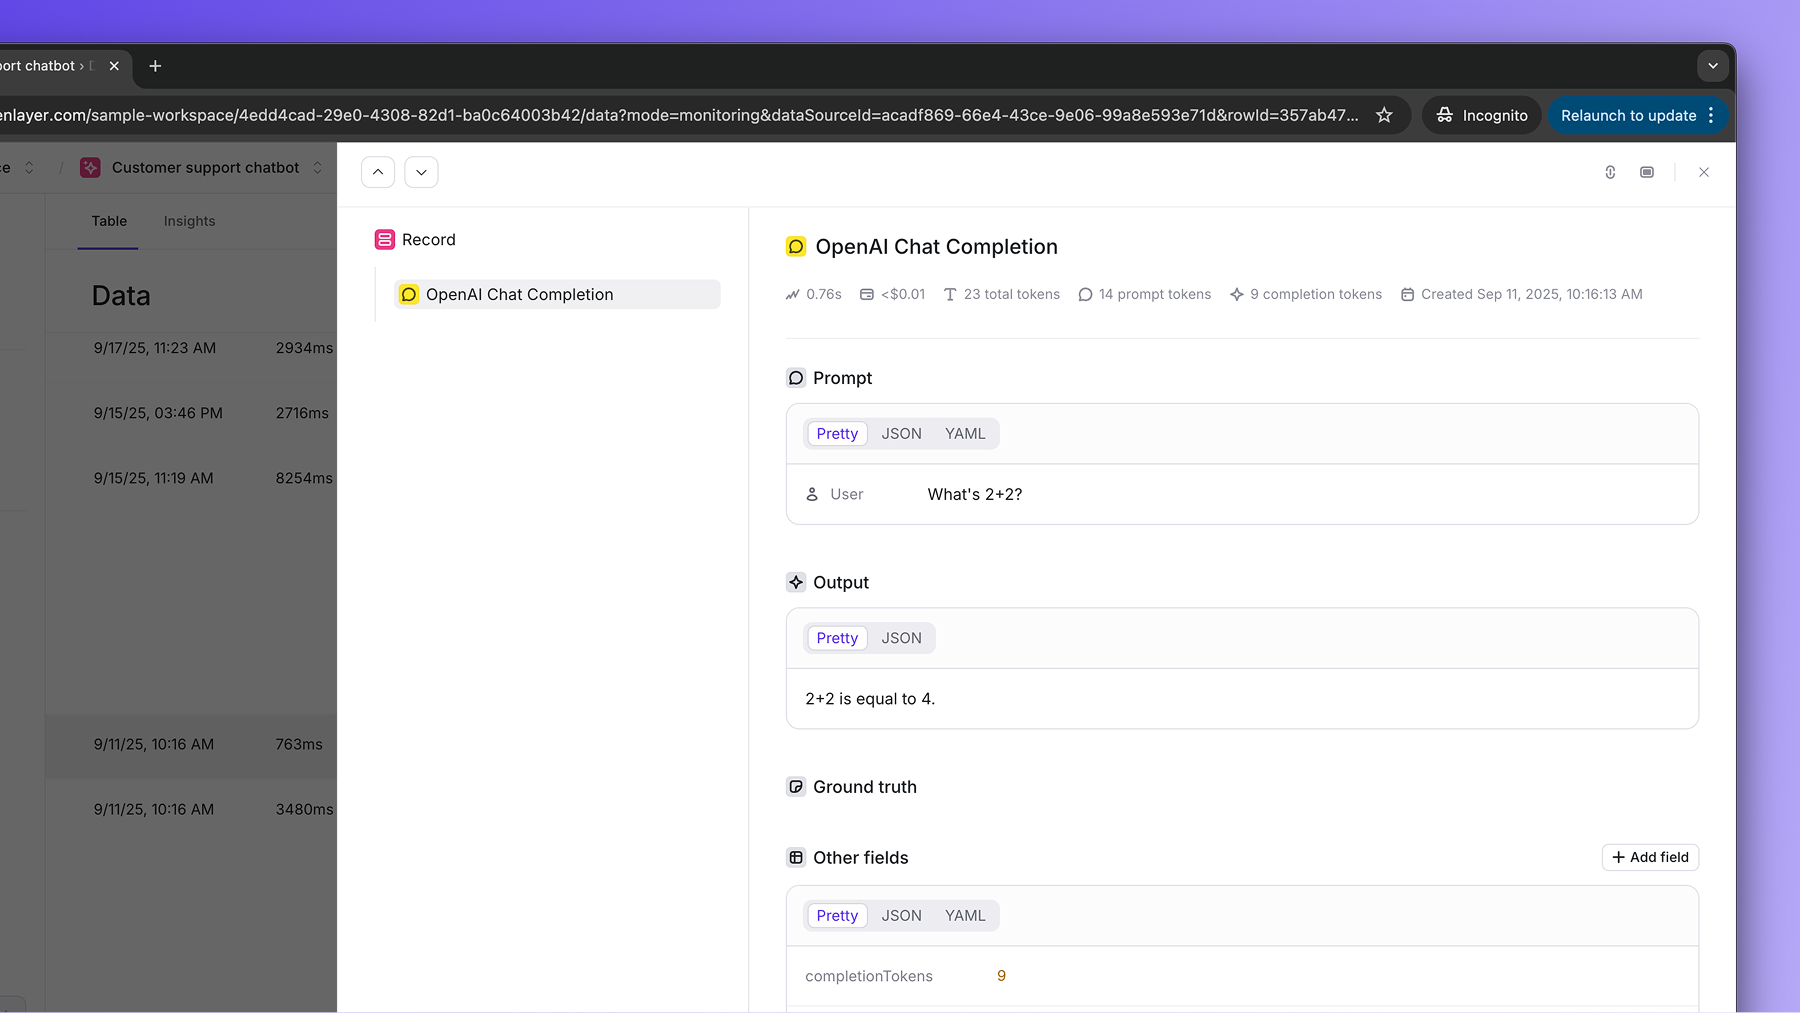
You can set up Openlayer tests to evaluate your OpenAI LLMs in monitoring and development.Monitoring
To use the monitoring mode, you must instrument your code to publish the requests your AI system receives to the Openlayer platform. To set it up, you must follow the steps in the code snippet below:See full Python example
See full TypeScript example
For Azure OpenAI, check out this code
example
instead.
If the OpenAI LLM call is just one of the steps of your AI system, you can use
the code snippets above together with tracing. In this
case, your OpenAI LLM calls get added as a step of a larger trace.
Embeddings
Embedding calls are traced as well.init() instruments the OpenAI,
AzureOpenAI, AsyncOpenAI, and AsyncAzureOpenAI clients, so every
embeddings.create call becomes a dedicated embedding step in the trace, with
the model, input, token counts, and the dimensions and number of vectors
returned:
Development
In development mode, Openlayer becomes a step in your CI/CD pipeline, and your tests get automatically evaluated after being triggered by some events. Openlayer tests often rely on your AI system’s outputs on a validation dataset. As discussed in the Configuring output generation guide, you have two options:- either provide a way for Openlayer to run your AI system on your datasets, or
- before pushing, generate the model outputs yourself and push them alongside your artifacts.
OPENAI_API_KEY
variable.
For Azure OpenAI, add the
AZURE_OPENAI_API_KEY, and AZURE_OPENAI_ENDPOINT
secrets instead.Using OpenAI LLMs as the LLM judge
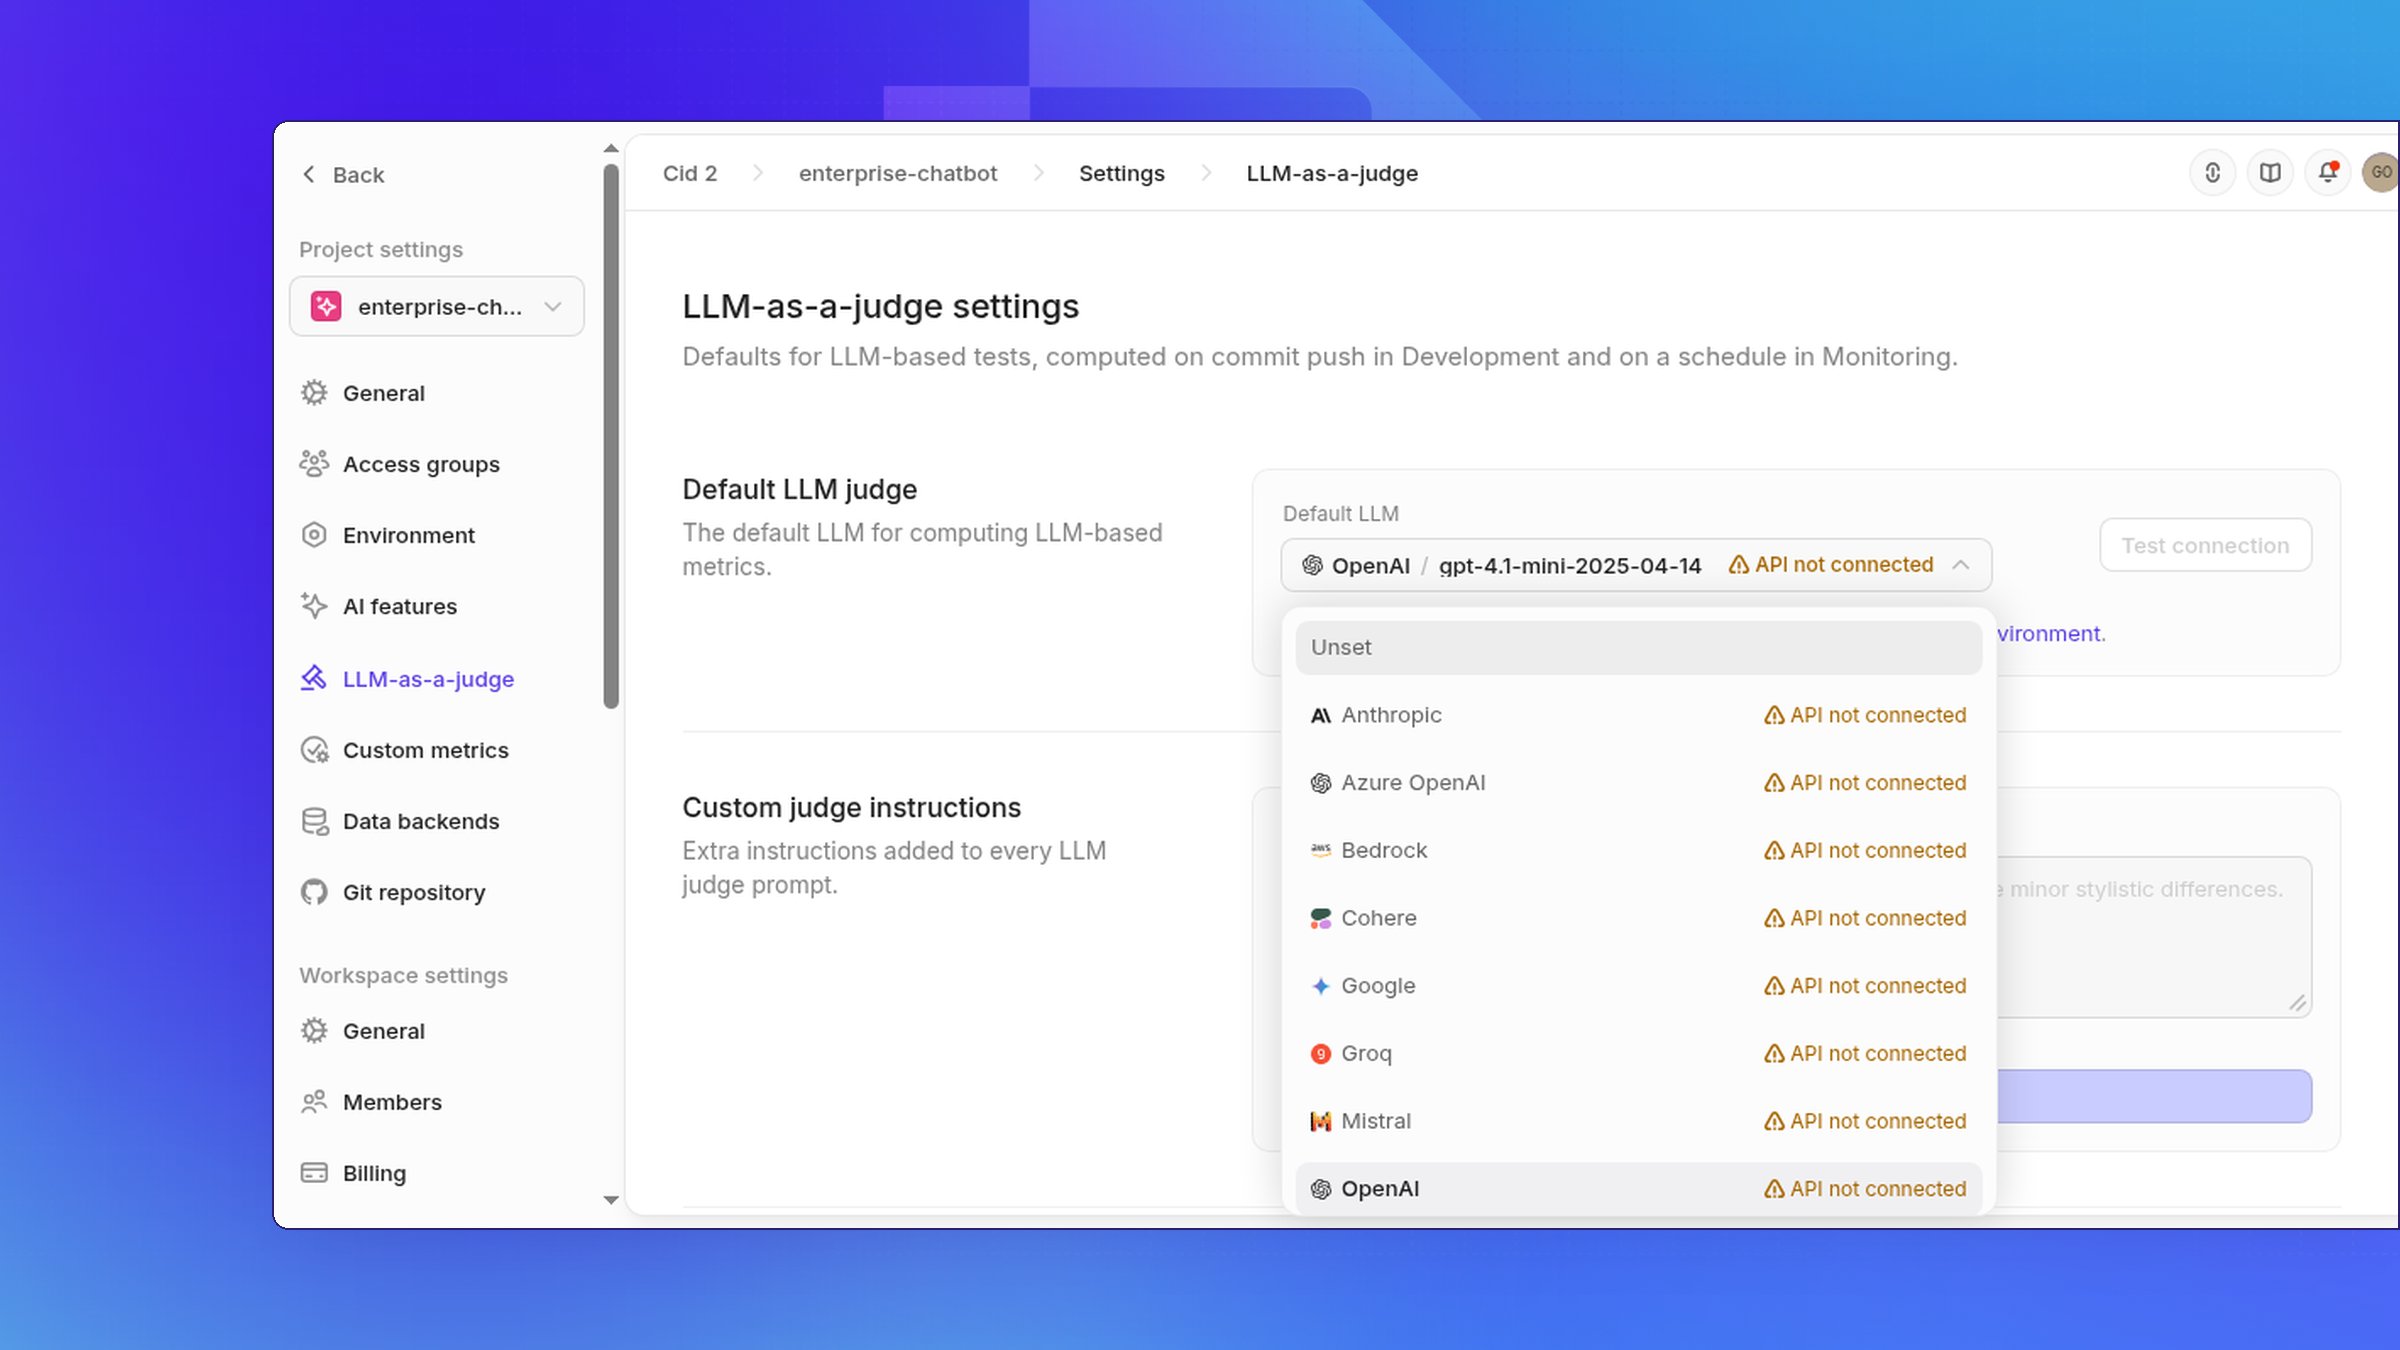
Some tests on Openlayer rely on scores produced by an LLM judge. For example, tests that use Ragas metrics and the custom LLM evaluator test. You can use any of OpenAI’s LLMs as the underlying LLM judge for these tests. First, addOPENAI_API_KEY under Settings → Environment at the workspace or
project level. Provider keys are not entered on the LLM-as-a-judge page.
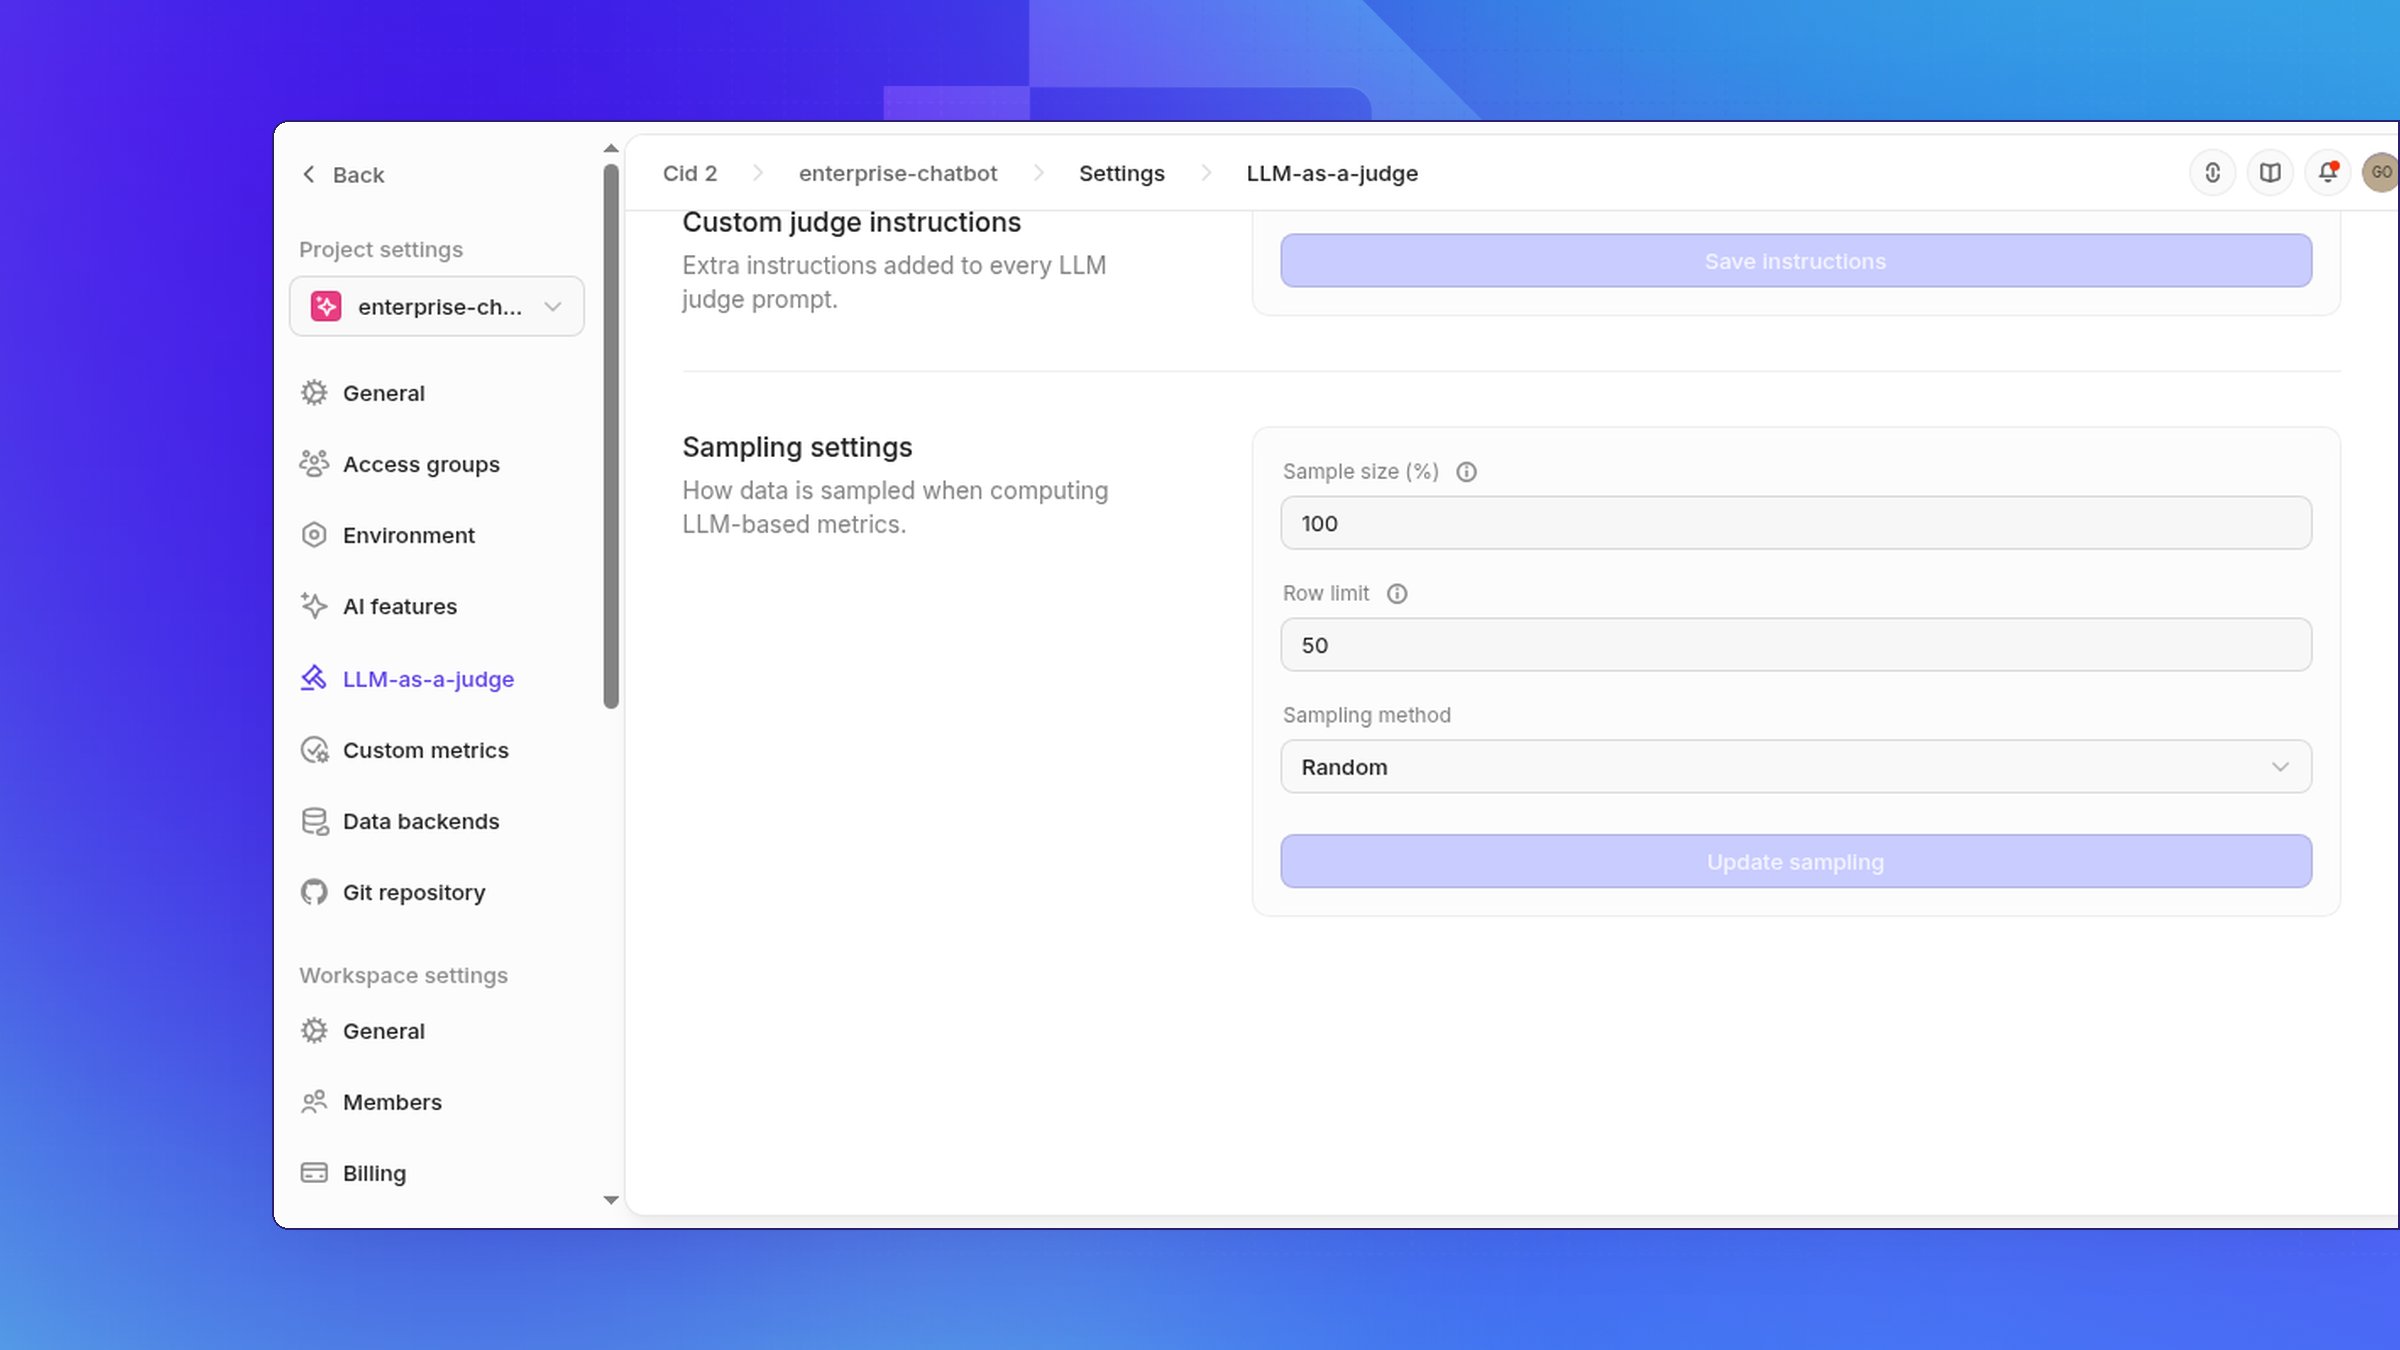
Open your project and go to Settings → LLM-as-a-judge. Under Default
LLM, choose OpenAI, type an OpenAI model name, and select Select.